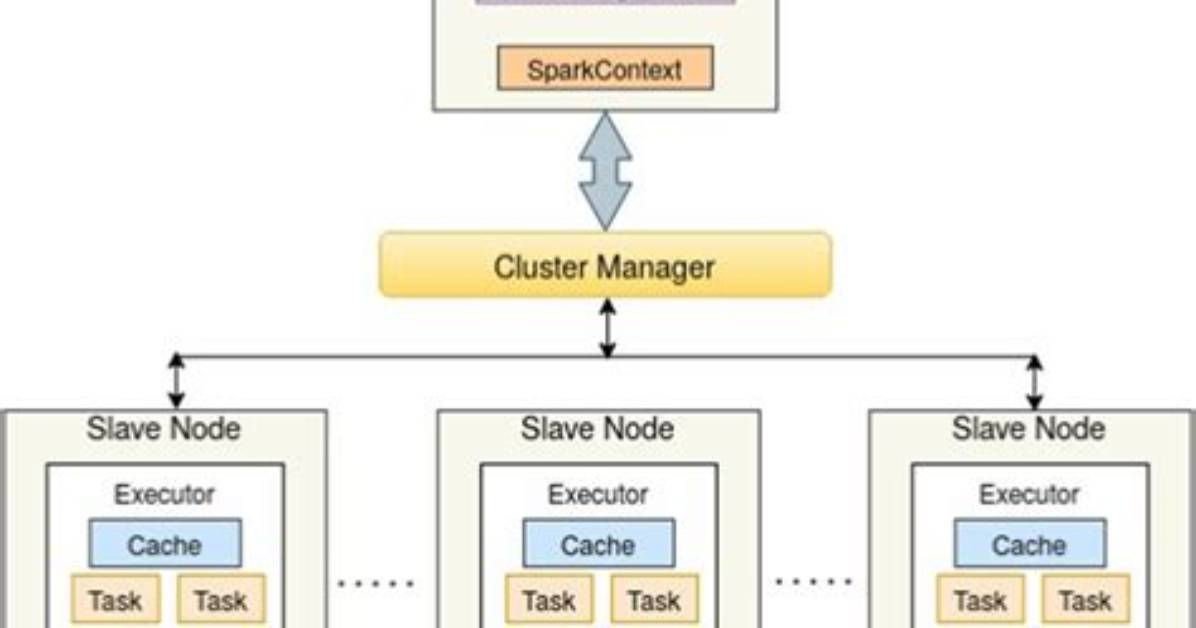
Memory per executor Spark is a critical configuration parameter that can have a significant impact on the performance of a Spark application. The amount of memory allocated to each executor determines how much data it can hold in memory, which in turn affects how often it needs to spill data to disk. Spilling data to disk is a slow and expensive operation, so it is important to allocate enough memory to each executor to avoid excessive spilling.
- Data size: The amount of data that will be processed by the application.
- Executor count: The number of executors that will be used by the application.
- Overhead: The amount of memory that is required by the application for overhead purposes, such as storing cached data and managing internal data structures.
- Concurrency: The number of tasks that will be running concurrently on each executor.
- Data locality: The degree to which the data that will be processed by each executor is local to that executor.
- Shuffle: The amount of data that will be shuffled between executors during the course of the application.
When determining the amount of memory to allocate to each executor, it is important to consider all of these factors. By carefully considering these factors, you can ensure that your Spark application has enough memory to perform efficiently without excessive spilling.
Data size
The amount of data that will be processed by the application is a critical factor in determining the amount of memory to allocate to each executor. If the data size is too large, the executors will not have enough memory to hold all of the data in memory, which will lead to excessive spilling to disk. This can significantly degrade performance.
- Title of Facet 1
Facet 1: If the data size is too small, the executors will not be able to fully utilize their memory, which can also lead to decreased performance. This is because the executors will be spending more time waiting for data to be processed than they are actually processing data.
- Title of Facet 2
Facet 2: The data size can also affect the number of executors that are needed to process the data. If the data size is too large, more executors will be needed to process the data in a reasonable amount of time. This can increase the cost of running the application.
- Title of Facet 3
Facet 3: The data size can also affect the type of storage that is used to store the data. If the data size is too large, it may not be possible to store the data in memory, and it may need to be stored on disk. This can also impact the performance of the application.
Therefore, it is important to consider the data size when determining the amount of memory to allocate to each executor. By carefully considering the data size, you can ensure that your Spark application has enough memory to perform efficiently without excessive spilling.
Executor count
The number of executors that will be used by the application is another critical factor in determining the amount of memory to allocate to each executor. If there are too few executors, the application will not be able to process the data quickly enough, and it will be underutilized. This can lead to decreased performance.
- Facet 1: Executor Cores
The number of cores on each executor can affect the amount of memory that is needed. If each executor has a large number of cores, it will need more memory to process data in parallel. This is because each core will need its own memory to store data and instructions.
- Facet 2: Executor Overhead
Each executor has some overhead associated with it, such as the memory that is used to store the executor's state and the memory that is used to manage the executor's tasks. This overhead can vary depending on the type of executor that is being used.
- Facet 3: Data Locality
The data locality of the application can also affect the number of executors that are needed. If the data is local to the executors, then the executors will not need to spend as much time fetching data from remote locations. This can improve performance and reduce the amount of memory that is needed.
- Facet 4: Shuffle
The amount of data that is shuffled between executors can also affect the number of executors that are needed. If there is a lot of shuffling, then more executors will be needed to process the data in a reasonable amount of time. This can increase the amount of memory that is needed.
Therefore, it is important to consider the number of executors that will be used by the application when determining the amount of memory to allocate to each executor. By carefully considering the number of executors, you can ensure that your Spark application has enough memory to perform efficiently without excessive spilling.
Overhead
Overhead is a critical factor to consider when determining the amount of memory to allocate to each Spark executor. Overhead can vary depending on the application, the data being processed, and the Spark configuration. Some common sources of overhead include:
- Cached data: Spark can cache data in memory to improve performance. The amount of memory used for caching can be controlled using the `spark.memory.fraction` and `spark.memory.storageFraction` configuration properties.
- Internal data structures: Spark uses a variety of internal data structures to manage data and tasks. The amount of memory used for these data structures can vary depending on the application and the data being processed.
- Executor JVM: Each executor runs in its own JVM. The JVM has its own overhead, which can vary depending on the JVM version and configuration.
- Other overhead: There are a number of other factors that can contribute to overhead, such as the number of tasks running on each executor, the amount of data being shuffled between executors, and the use of custom code or libraries.
It is important to consider overhead when determining the amount of memory to allocate to each executor. If each executor is allocated too little memory, it will not be able to run the application efficiently. This can lead to decreased performance, increased spilling, and longer job completion times.
Concurrency
Concurrency is an important factor to consider when determining the memory per executor Spark. The number of tasks that will be running concurrently on each executor will affect the amount of memory that is needed by each executor. If there are too many tasks running concurrently on each executor, the executors will not have enough memory to run the tasks efficiently. This can lead to decreased performance and increased spilling.
For example, if you are running a Spark application that processes a large amount of data, you may need to increase the number of executors and the amount of memory per executor in order to ensure that the application runs efficiently. This is because each executor will need to have enough memory to hold the data that it is processing, as well as the memory that is needed to run the tasks that are running on the executor.
On the other hand, if you are running a Spark application that processes a small amount of data, you may be able to get away with using a smaller number of executors and a smaller amount of memory per executor. This is because each executor will not need as much memory to hold the data that it is processing, and there will be fewer tasks running concurrently on each executor.
Ultimately, the amount of memory per executor Spark that you need will depend on the specific application that you are running and the amount of data that you are processing. It is important to experiment with different values to find the optimal setting for your application.
Data locality
Data locality is an important factor to consider when determining the memory per executor Spark. The degree to which the data that will be processed by each executor is local to that executor will affect the amount of memory that is needed by each executor. If the data is local to the executor, the executor will not need to spend as much time fetching data from remote locations. This can improve performance and reduce the amount of memory that is needed.
- Facet 1: Reduced Network Traffic
When data is local to an executor, it does not need to be transferred over the network to be processed. This can significantly reduce network traffic and improve the overall performance of the application.
- Facet 2: Improved Cache Hit Rate
When data is local to an executor, it is more likely to be cached in memory. This can improve the cache hit rate and reduce the amount of time that is spent fetching data from disk.
- Facet 3: Reduced Memory Overhead
When data is local to an executor, the executor does not need to maintain as much memory overhead for network buffers and other data structures. This can reduce the overall memory footprint of the application.
- Facet 4: Improved Scalability
When data is local to an executor, the application can scale more easily by adding more executors. This is because the executors will not need to spend as much time fetching data from remote locations.
Therefore, it is important to consider data locality when determining the memory per executor Spark. By carefully considering data locality, you can ensure that your Spark application has enough memory to perform efficiently without excessive spilling.
Shuffle
When data is shuffled between executors, it is typically stored in memory on the source executor and then transferred to the destination executor over the network. This can put a strain on the memory resources of both the source and destination executors, especially if the amount of data being shuffled is large.
- Facet 1: Shuffle Spill
If the amount of data being shuffled is too large to fit in memory, it will be spilled to disk. This can significantly degrade performance, as disk I/O is much slower than memory access.
- Facet 2: Executor Memory Overhead
Each executor must maintain a certain amount of memory overhead for shuffle data. This overhead can vary depending on the amount of data being shuffled and the type of shuffle operation being performed.
- Facet 3: Network Overhead
Shuffling data over the network can also incur significant overhead. This overhead can be reduced by using a fast network interconnect, such as InfiniBand or Ethernet with RDMA.
- Facet 4: Impact on Memory per Executor
The amount of shuffle data can have a significant impact on the amount of memory that is needed per executor. If the amount of shuffle data is large, it may be necessary to increase the amount of memory allocated to each executor.
Therefore, it is important to consider the amount of shuffle data when determining the memory per executor Spark. By carefully considering the amount of shuffle data, you can ensure that your Spark application has enough memory to perform efficiently without excessive spilling.

